I’ve blathered before about how hard it is to do traffic stats these days — AI scrapers run full browsers via VPNs with residential endpoints. So you can’t distinguish them from real traffic, really.
I mean, none of this matters, but…
One trick that really helps weed out scrapers from the stats is to just not “count” a web page visit until the page has been open for more than ten seconds. Yes, you lose real readers that bounce fast, but whatevs.
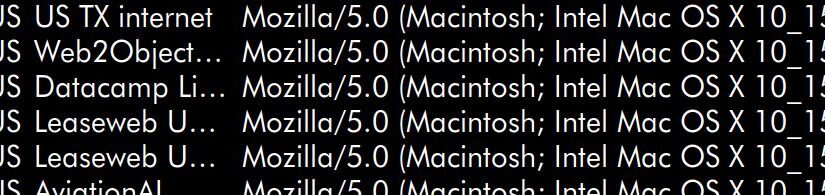
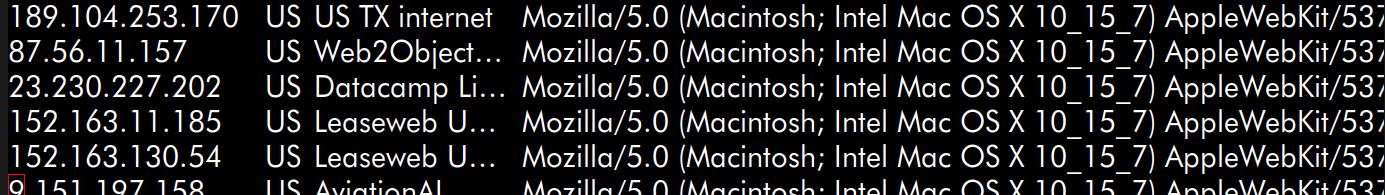
However, there are scrapers (as shown in the above screenshot). That’s a pretty typical trace — you get dozens of hits from all over the world to the same obscure blog post, but using the same User-Agent.
What I was idly curious about was this: Since I’m using a setTimeout to register the page view, are these scrapers really keeping a web browser open for ten seconds? Or are they just collapsing setTimeout calls and doing everything immediately? (That’s certainly what I’d do if I were an evil scraper.)
So I had a look at my Apache logs, and:
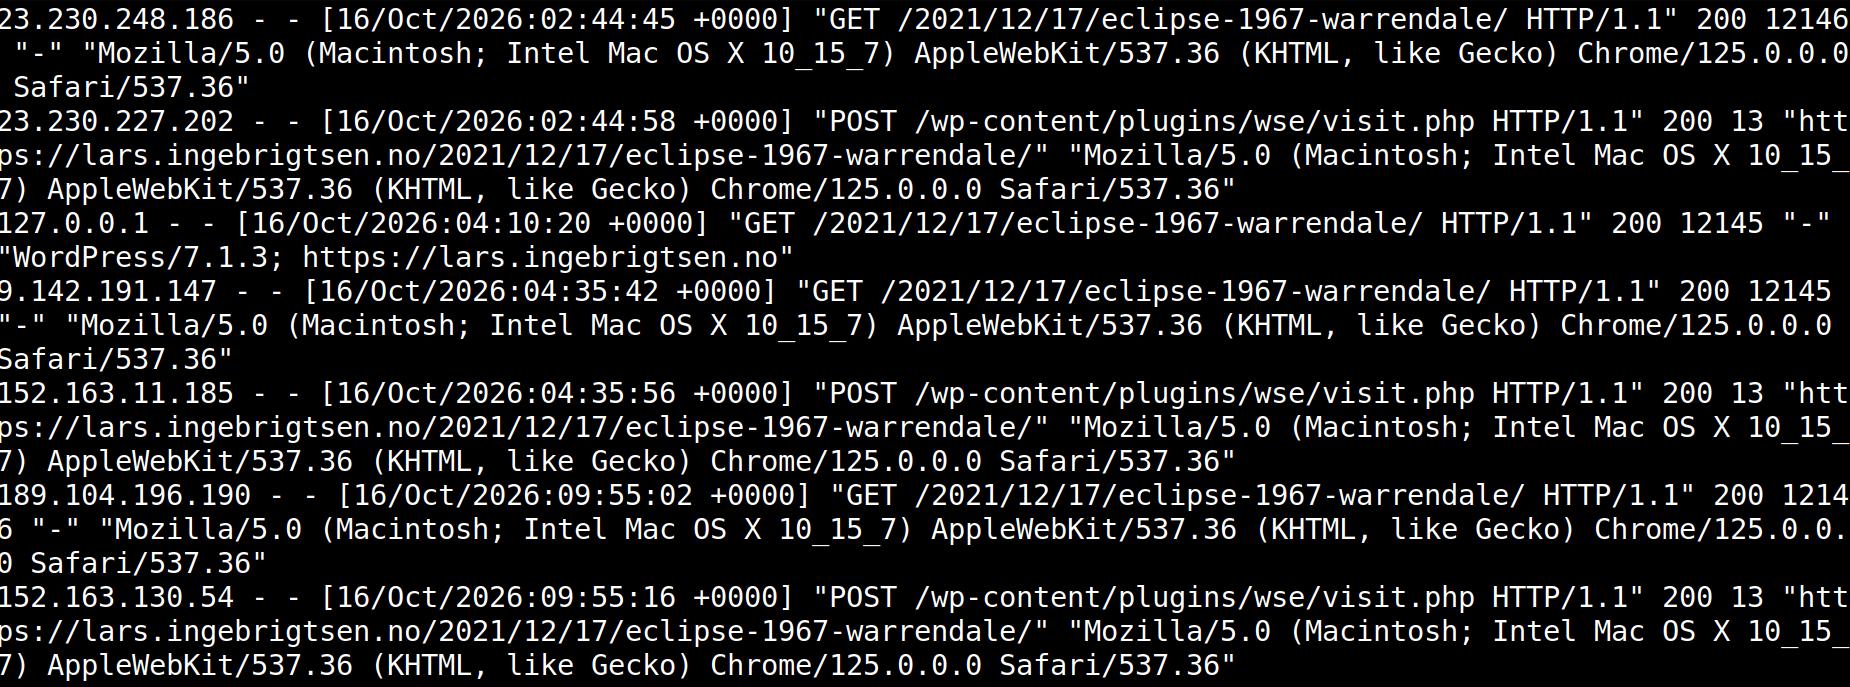
Yeah, it’s a real browser with no collapsing of the setTimeout values.
I checked a couple more, but they show the same pattern.
So there you go — these scraper people have way too many resources to burn.